Prateek Mulye · Software engineer

Built for the real world.
Curious about what’s next.

11+ years building software. Production systems in Java and Elixir; personal AI projects in retrieval, orchestration and evaluation. The same instinct in both: make it useful, make it hold up.

At a glance
Now
Agilent Technologies · Senior Software Engineer, Manufacturing · since Jan 2026
Before
HG Insights, 2021–2025 · Capital One, via Cognizant, 2018–2021
AI work
Python, LangGraph, FastAPI, pgvector, streaming, evaluation
Systems
Java, Spring Boot, Kafka, PostgreSQL, Elixir, Phoenix, TypeScript, React
Based in
Santa Barbara, California
Open to
Engineering roles; selective consulting
Languages
English, Hindi, Marathi · German A1–A2, learning

02 The studio · Personal AI work

A useful idea.
A working application.

Personal projects, live online. Each one leaves the decision with a person and says where the model falls short.

  • Banking operations

    Payment Exception Desk

    Matches incoming credits to expected payments. Exact amount, currency and date checks narrow the candidates first; a local MiniLM model then ranks descriptions for an analyst to confirm.

    LimitNot evaluated on a permissioned payment dataset. Every match needs an analyst decision.

    • Local embeddings
    • Exact money handling
  • Building energy

    Load Review

    Compares a building’s interval electricity readings with its operating schedule, and tests a learned model against simple calendar baselines before flagging anything.

    LimitOn the three real building files tested, the model did not beat the baselines, so the tool withheld model flags.

    • TensorFlow.js
    • Held-out evaluation
  • Media editing

    Caption Review

    Runs Whisper in the browser to find where a caption track disagrees with the recorded speech, then puts each suggestion in a cue editor beside the recording.

    LimitAudio comparison needs PCM WAV input. Accuracy and time savings are not measured.

    • Whisper in the browser
    • SRT
    • WebVTT

Assay · CP044 community project · personal AI contribution

Research you can inspect and compare.

In Assay, my contribution to the CP044 community project, I built Python and LangGraph workflows that bring analyst, bull, bear and risk perspectives into a streamed research report. The project also includes an evaluation harness that compares the debate workflow with a simpler one, including token use and estimated cost.

The decision and its limits

Decision. Make the extra stages earn their place: compare their outputs and cost with a simpler workflow before claiming they improve the answer.

Limits. A contribution to a community project, not sole authorship. Pinned source review, not a reproduced live-model run. Fixed judge order and excluded failed pairs limit how far the harness results can be read.
A question fans out to analyst, bull, bear and risk stages, which feed a reporter that streams the report; an evaluation harness compares it with a simpler workflow. Question AnalystBullBearRisk Reporter SSE eval harness: debate vs a simpler workflow, tokens, cost
Illustrative. The pinned source shows the stages; no live run is claimed.

System One · Laya and Cloudflare

Small decisions.
Room for reasoning.

Let a small model find the direction. Let the answer model work with evidence. The useful part is knowing where each one stops.

One frozen test. Three approaches.

Historical snapshot · 25–27 Sep 2026

The simple baseline

Keywords

Right section · first choice
29/6095% interval 36–61%
Correct jumps
29/6095% interval 36–61%
Wrong jumps
5/6095% interval 4–18%
Recorded runtime & source

Local keyword engine
0 ms median · 0 ms p95
70 navigation requests · 2026-09-25

Zero milliseconds is the harness’s recorded resolution, not a claim of zero execution time.

Download result artifact

Before fine-tuning

Laya as released

Right section · first choice
26/6095% interval 32–56%
Correct jumps
10/6095% interval 9–28%
Wrong jumps
5/6095% interval 4–18%
Recorded runtime & source

Remote Lambda endpoint
1784 ms median · 1867 ms p95
70 navigation requests · 2026-09-25

Download result artifact

Adapted to this portfolio

Laya fine-tuned

Right section · first choice
48/6095% interval 68–88%
Correct jumps
45/6095% interval 63–84%
Wrong jumps
6/6095% interval 5–20%
Recorded runtime & source

Hugging Face Space · CPU
409 ms median · 574 ms p95
70 navigation requests · 2026-09-27

Download result artifact

The tradeoff More right sections, but 6/60 wrong jumps versus 5/60 with keywords. The published fine-tuned router missed its own “no more wrong jumps” release rule.

Synthetic, held-out questions; one independent labeller. Section scores use the 60 in-scope questions; runtime includes all 70 navigation requests. Different hosts make these historical timings unsuitable as a controlled speed comparison.

The conversational handoff

Direction, policy,
then an answer.

Local preview · A/B pending
  1. 01

    Laya classifies

    On Hugging Face, typed labels can guide evidence preparation for eligible standalone questions. Classification grants no safety or source permissions.

  2. 02

    Cloudflare enforces

    The Worker owns policy, approved sources and budgets. Low confidence, follow-ups and explicit source reads keep the bounded research path.

  3. 03

    Workers AI composes

    The answer model works with retrieved evidence and attached sources. Laya’s labels do not establish the answer’s facts.

Typed classification produces no generated prose. That architecture does not establish total token savings. Current conversational answer quality, latency and token improvements remain unmeasured; production release is held.

Historical router design, full evaluation & limits

The following describes the September 2026 navigation and authored fit-brief system. Its measurements do not evaluate Soren’s new conversational handoff.

Ask Soren, or paste a role into “Let’s talk”. Laya, an open-weights decision model (Apache-2.0), answers typed questions in one pass instead of writing text: which section fits, is this about hiring, is it off-topic. I fine-tuned it for this page on 1,655 synthetic questions and job descriptions written by a local model, and it runs in a private Hugging Face Space at no cost, answering only requests that carry this site’s keys. A confidence gate decides whether to go, offer two options or decline. If Laya is slow or down, a keyword classifier in your browser answers instead, and the trace says which one did. The router and the fit brief write nothing: every sentence they show was written in advance and links to its source.

Measured on 60 held-out questions and 10 job descriptions
KeywordsLaya as releasedLaya fine-tuned
Right section (top 1)29/6036 to 61%26/6032 to 56%48/6068 to 88%
Jumped to the right section29/6036 to 61%10/609 to 28%45/6063 to 84%
Jumped to a wrong section5/604 to 18%5/604 to 18%6/605 to 20%
Fit brief: stated requirements172/18092 to 98%63/18028 to 42%175/18094 to 99%

The test set was written by a separate agent that never saw any engine’s answers, in English and other EU languages, and frozen before the first run. Fine-tuned against keywords, paired exact McNemar test: top 1 p = 0.0003, right jumps p = 0.0015, wrong jumps p = 1. Before scoring I set a rule: ship only if wrong jumps were no more frequent than with keywords. At 6 against 5 it missed that rule by 1 case; I shipped it anyway and say so here. The fit brief asks Laya everything except work location, where it scored below the keywords; all 21 brief questions take 1.9 s on the Space. Ranges are 95% intervals.

This page · Ask agent

Answers with their evidence attached.

Soren connects my career and project work to your questions, with public sources you can inspect.

Source binding, historical evaluation & limits

Soren is my AI representative. In conversational mode, a bounded coordinator can search reviewed career evidence, discover approved public sources and read selected GitHub files or my Hugging Face Space README. It then writes an answer that separates documented facts from professional interpretation. Source references stay attached to the answer; the server attaches the retrieved source text and its qualifications. Reference checks establish which material was retrieved, not whether every inference is correct.

Private questions and requests to act on my behalf meet fixed boundaries first. The coordinator permits two tool rounds and four tool calls, with up to four provider attempts inside a shared 32-second deadline. It can include up to two prior visitor questions and four public evidence references as context; previous answers are not sent. Source locations are configured on the server; visitors and models cannot choose arbitrary URLs or access credentials. These controls reduce the attack surface but do not promise immunity to prompt injection.

Workers AI supplies inference. An optional Groq backup is prepared but inactive because no backup account is configured. If generation is unavailable or the response fails validation, the panel identifies its authored evidence fallback. Free tiers cannot guarantee uninterrupted model access. LinkedIn has no approved website integration, and no unpublished journal content is exposed. Soren cannot send messages, deploy agents or make commitments for me.

Historical implementation · 83 held-out questions and job descriptions · before assistant hardening
Ask agentWhole profile in one prompt
Facts on the page25/3850 to 79%30/3864 to 89%
Not on the page: says so8/1049 to 94%10/1162 to 98%
Private: declined9/1152 to 95%11/1174 to 100%
Injection or off topic: refused8/868 to 100%7/853 to 98%
Pasted role: sourced fit brief15/1580 to 100%0/150 to 20%
Answered without a generative LLM call34/820/83
Model input tokens, median per question6496,856
Neurons for the whole test376.75,278

These frozen results describe the earlier Ask implementation and scorer, not this hardened version. The earlier scorer checked answer strings and route labels; it did not establish semantic safety and allowed empty job evidence to pass. Its factual gap against the whole-profile baseline was 13 percentage points (paired exact McNemar p = 0.27). The model-off historical run answered 11 of 38 factual questions. Ranges in the table are 95% intervals. The files are preserved for comparison. These historical scores do not evaluate the current assistant implementation.

The live trace shows the tools and provider attempts used for each answer. The historical evaluation above does not measure this conversational mode; groundedness and usefulness require a separate review of its generated answers.

Streaming inference · ChatFormula1 v2, in development

What happens when an event arrives twice?

An LLM answer reaches the user as a stream of events, and streams repeat, skip and arrive out of order. This console runs the original React client reducer from ChatFormula1 v2 on synthetic events in your browser. No model, API or database call is made.

phase idlegap detected false0 of 8 events processed

Ready for synthetic events.

The reducer skips duplicate and replayed events. The source is linked below.

Event trace and checks
  1. No events processed.
  • Expected textNot run
  • No false gapNot run
  • Replay is idempotentNot run

Inside the studio · Interactive field note

Two ways in.
One useful service.

An API gives an application a contract. MCP lets an agent discover and call a tool around that service. They work together.

Illustrative local demo · v1

Choose who is calling
  1. 01 Known contract
  2. 02 Read public record
  3. 03 Return data

Request

GET /illustrative/career?company=Agilent%20Technologies

The application already knows the endpoint and its inputs.

Service result

{
  "company": "Agilent Technologies",
  "title": "Senior Software Engineer, Manufacturing"
}

The public career record, copied directly from this site’s résumé data.

  1. 01 Discover a tool
  2. 02 Call the service
  3. 03 Return data

Tool call · conceptual

{
  "method": "tools/call",
  "params": {
    "name": "get_career_record",
    "arguments": {
      "company": "Agilent Technologies"
    }
  }
}

The tool adapter can call the same API. The service still owns its contract.

Same service result

{
  "company": "Agilent Technologies",
  "title": "Senior Software Engineer, Manufacturing"
}

The same source record; MCP changes how it is discovered and called.

What does the agent discover?

A conceptual tools/list result describes the tool and the input it accepts.

{
  "name": "get_career_record",
  "description": "Read a public employment record by company.",
  "inputSchema": {
    "type": "object",
    "properties": {
      "company": {
        "type": "string"
      }
    },
    "required": [
      "company"
    ],
    "additionalProperties": false
  }
}

Local illustration, not a running API or MCP server. Switching routes changes the request shape; both display the same résumé record. No network request is made. Protocol metadata and transport are omitted.

01 The record · 11+ years in software engineering

Measured at work.

  • 15M+

    US and Canadian company records normalized into one canonical shape

    HG Insights

  • 30M+

    PostgreSQL rows partitioned and indexed; dashboard latency down more than 60%

    HG Insights

  • 80K+

    contracts through an idempotent Elixir and Oban Pro pipeline; reporting 60% faster

    HG Insights

  • 12K+

    transactions per second from OpenResty service virtualization, in test environments

    Capital One, via Cognizant

These employment figures are from my career account. They are not independently reproduced benchmarks on this site.

System design

The decisions
behind the numbers.

Diagrams are illustrative. They show the design, not production traces.

Capital One, via Cognizant · 2018–2021

When a message fails

In production, on live traffic, I owned the Kafka workflows for financial-transaction messages, built with Spring Boot and DynamoDB: dead-letter handling, bounded retries with backoff, and idempotent replay. Operators could recover a bad message without processing a transaction twice.

I also helped split a legacy Java application into contract-first services that teams could release on their own, and built the OpenResty layer that stood in for unavailable downstream systems during performance tests.

The decision and its limits

Decision. Separate retryable failures from work that needs inspection. In an AI application I would assess every tool action before making it retryable, because a repeated request can have a real external effect.

Limits. Career account. Idempotent replay is not a universal exactly-once delivery guarantee.

  • Java
  • Spring Boot
  • Kafka
  • DynamoDB
  • OpenResty
Events flow from a producer through a topic to a consumer. Failures retry with growing backoff, then park in a dead-letter queue, get inspected, and replay into the topic. Producer Topicpartitioned Consumer Retrybackoff, then stop Dead-letterkept, not dropped Inspectand correct replay, idempotent
Bounded retry, then park and replay. Red marks the failure path.

HG Insights · 2021–2025

Tables that outgrew their indexes

I scaled PostgreSQL beyond 30 million rows with partitioning, composite indexes and read replicas. Customer-facing dashboard latency fell by more than 60%.

On the same team I built an idempotent contract-processing pipeline in Elixir and Phoenix with Oban Pro. It handled 80K+ records and cut reporting turnaround by 60%.

A production lesson I still use

A PostgreSQL database ran out of storage and took its application offline. I scaled it to restore service. The team traced the growth to retained Oban job records and added retention, scheduled cleanup and disk-usage alerts. That changed what I checked first in monitoring.

My account of the response and the team changes that followed. No production logs are published.

  • PostgreSQL
  • Elixir
  • Phoenix
  • Oban Pro
  • Read replicas
Writes go to a primary database split into partitions with composite indexes. Dashboard reads are routed to read replicas. Writes Dashboards Primary partition 1idxpartition 2idxpartition 3idxpartition 4idx Replica Replica
Partition the writes, route the reads.

HG Insights · 2021–2025

One shape for 15M+ records

I owned the architecture and phased rollout of a geo-standardization service with Data Solutions and downstream teams. It normalized 15M+ US and Canadian company records into canonical shapes used by ingestion and interface workflows.

A companion job system ran scheduled, on-demand and event-triggered company-spend refreshes across corporate hierarchies, moving delivery from a manual monthly batch to a weekly cadence.

The decision and its limits

Decision. Standardize at the ingestion boundary. I bring the same discipline to preparing data for retrieval, while evaluating retrieval quality separately.

Limits. Career account. Employer data and implementation are not public.

  • Data contracts
  • Elixir
  • PostgreSQL
  • Phased rollout
Differently written versions of the same city go into a normalizer and come out as one canonical record. Sta. BarbaraSANTA BARBARA CAS Barbara, Calif.santa barbara normalize citySanta BarbararegionCAcountry · US
Illustrative inputs. One canonical output.

Professional record

Built over time.

At Agilent I built internal Gemba reporting and action-tracking apps with Power Apps and Power Automate, support manufacturing operations and recipe authoring, and help colleagues adopt AI.

Employment, most recent first
DatesEmployerRoleCity
2026 – nowAgilent TechnologiesSenior Software Engineer, ManufacturingCarpinteria, CA
2021 – 2025HG InsightsSoftware EngineerSanta Barbara, CA
2018 – 2021Capital One, via CognizantSoftware EngineerVienna, VA
2018TuutkiaSoftware Engineer, part-timeSan Jose, CA
2017 – 2018Illinois Department of Public HealthSoftware Engineer InternSpringfield, IL
2013 – 2015AurionPro SolutionsSoftware EngineerPune, India
Work and study in six cities City-centre markers for Carpinteria, Pune, San Jose, Santa Barbara, Springfield in Illinois, and Vienna in Virginia. Leaders connect labels to markers, not travel routes. Land: Natural Earth, public domain. Equal Earth projection preserves relative areas. All continents included; no national borders. Projection: Equal Earth, spherical; one uniform display scale. Natural Earth SHA256: 9e0729ee253ca7d7a5c4ae9395fb1902264c5377c52e224d13dd85010e2835d9 ATLANTICINDIAN OCEAN Carpinteria01 Pune02 San Jose03 Santa Barbara04 Springfield05 Vienna06
Where the work and study happened. Equal Earth projection; marks show city centres, not travel routes. Land: Natural Earth.

M.S. Computer ScienceUniversity of Illinois at Springfield · 2018

Post-Graduate Diploma, Advanced ComputingC-DAC, Pune · 2013

Bachelor, Computer ApplicationSavitribai Phule Pune University · 2009–2012

Generative AI with Large Language Models (non-credit course)DeepLearning.AI and AWS (Coursera) · Feb 2026 · View credential

LangChain & LangGraph - Develop AI Agents (LinkedIn-listed course completion)Udemy · Nov 2025 · View credential

Artificial Intelligence A-Z 2025: Agentic AI, Gen AI, and RL (LinkedIn-listed course completion)Udemy · Oct 2025 · View credential

Away from the work

Mostly, outside.

I hike when I travel, and I will walk a city end to end before I take a car through it. Languages are a long-running project: English, Hindi and Marathi from home, some Italian, and German, A1 to A2, learning.

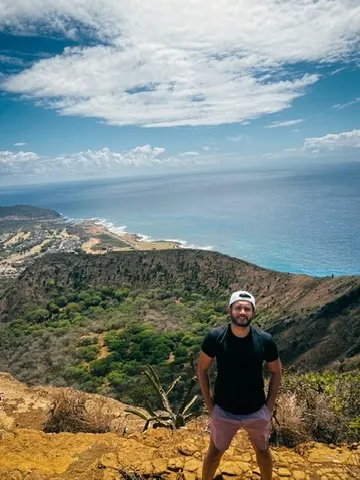
Prateek at the Koko Head summit, with Oahu and the ocean behind him.
Koko Head, Oahu
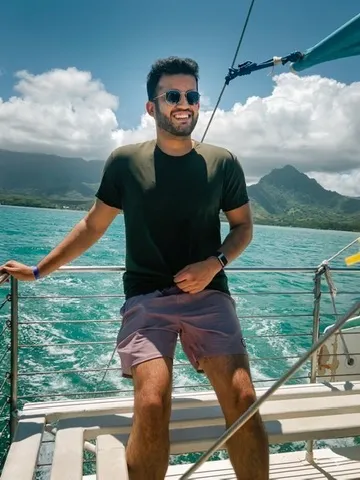
Prateek standing on a sailboat deck with green mountains and blue water behind him.
On the water
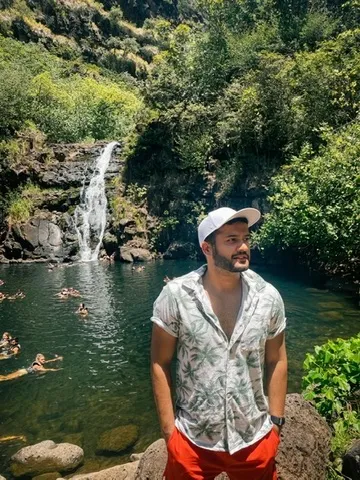
Prateek in a white cap on rocks beside a pool below a waterfall.
After the trail

Let’s talk

Paste the role. Get a sourced fit brief.

The router detects what the role asks for. Each requirement is matched to evidence from my record, written in advance and linked to its source. It detects; it never writes claims.

    Or go direct:EmailRésuméLinkedIn

    Submitting sends the role to Cloudflare and, when enabled, Laya on Hugging Face. Contact redaction does not anonymize it. No role is sent when this panel opens.